WaveGrating
A wave-optics renderer for Blender, in development.
Independent AI product engineer, Los Angeles
Selected workA wave-optics renderer for Blender, in development.
An image-to-3D extension with staged GPU memory use.
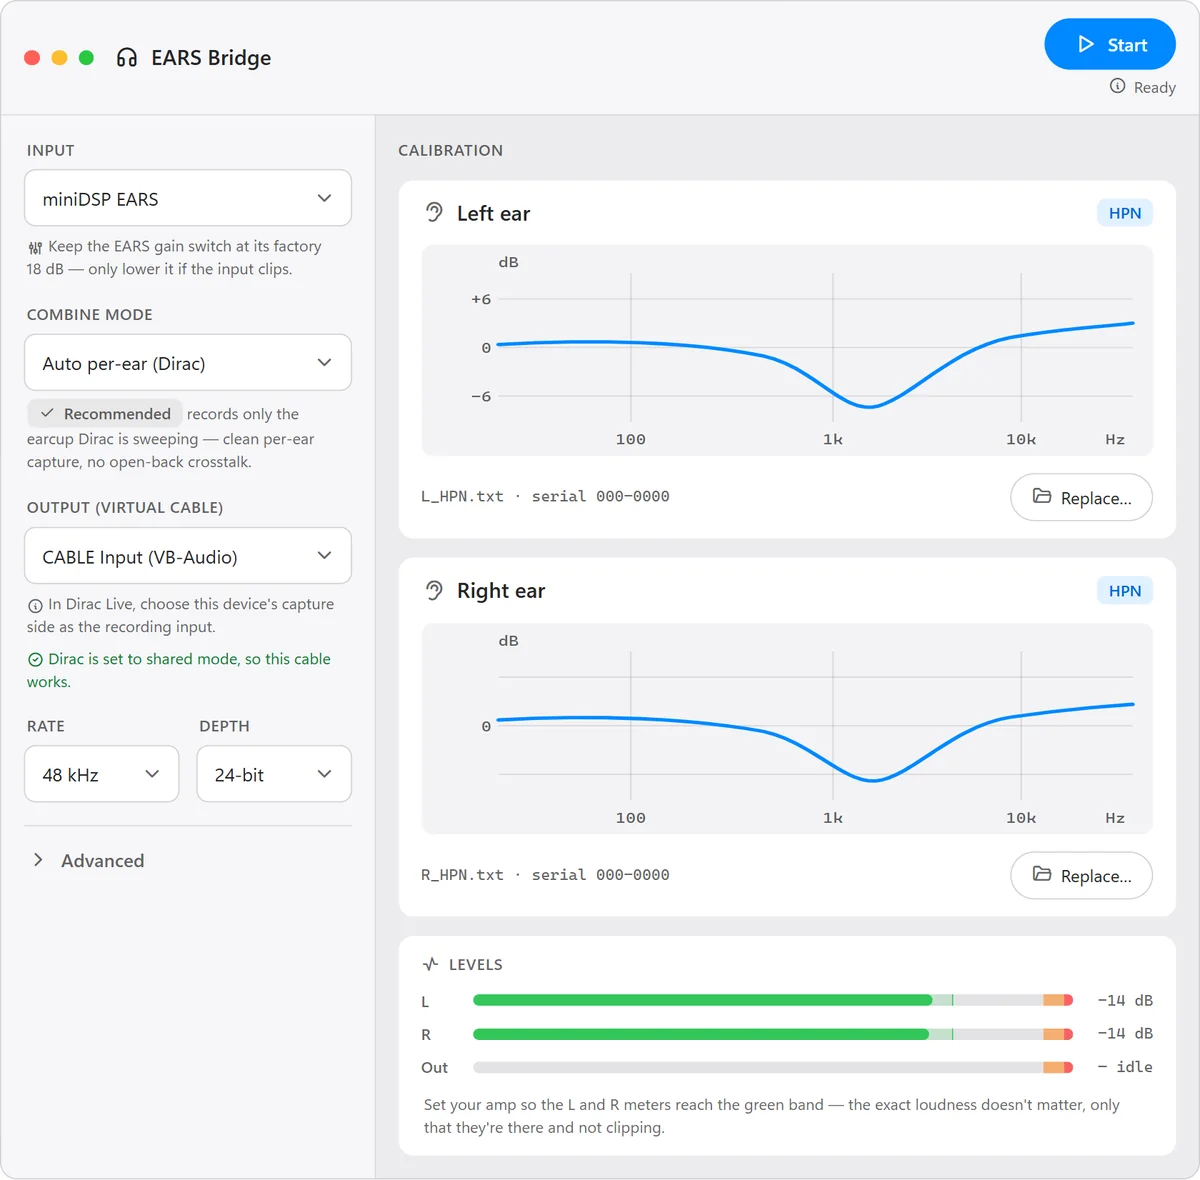
A headphone measurement bridge for Dirac Live.
A self-hosted AI model for coding tools.
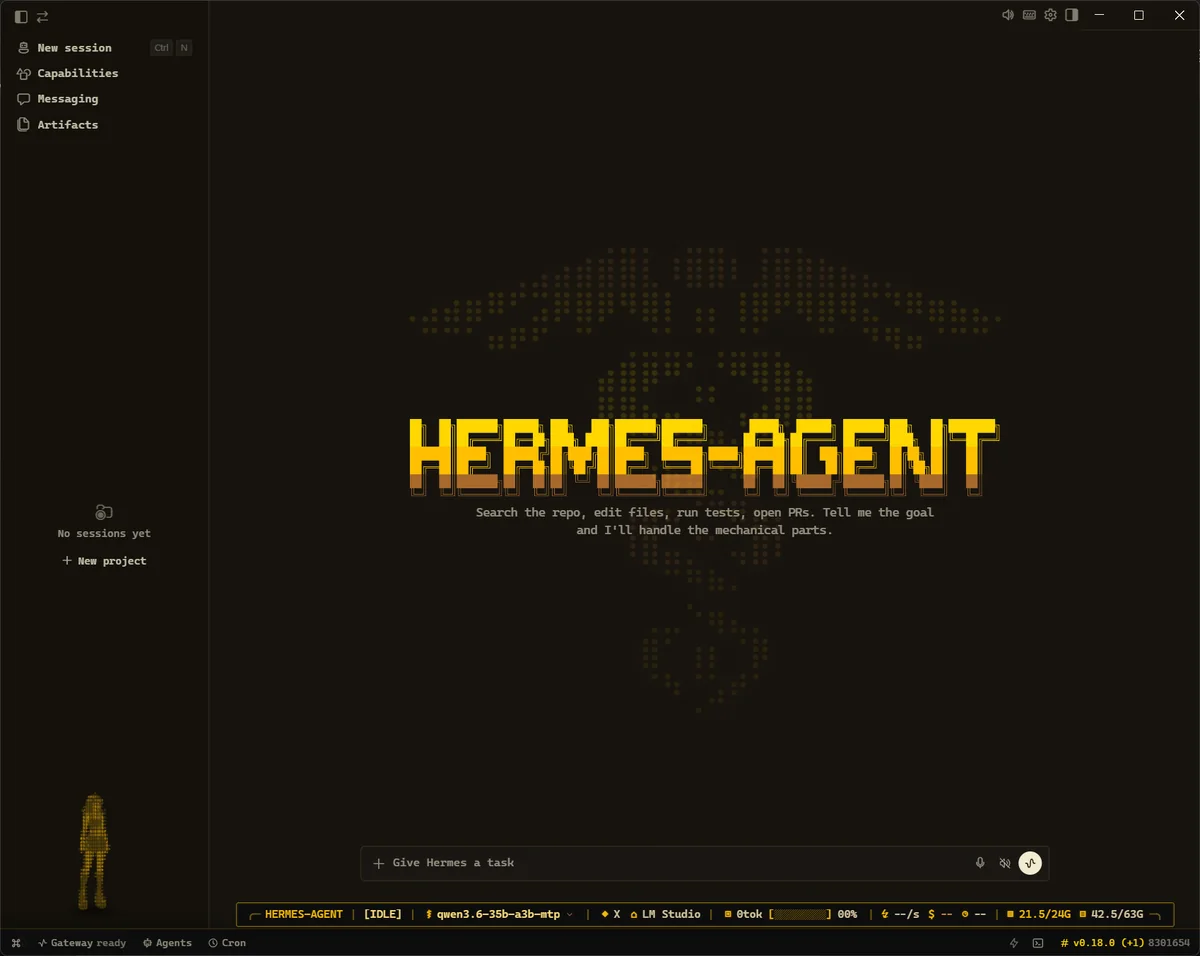
A gold theme and session telemetry for Hermes Desktop.
A context plugin for Hermes Agent.
When a tool I use breaks, I trace the fault and send its maintainers a fix or a field report. Of the five pull requests below, two are merged and three are in review.
The cache never hit on this recipe. With the fix, the time to first token for a repeated 262,144-token prompt fell from 191.7 s to 2.98 s.
Documents the load guard, the startup-check trap, and fault gating for the shared memory of a DGX Spark.
Weight loading copied the scales of every expert at once. On a test tensor one eighth of production size, memory growth fell from 1,011 MiB to 3 MiB.
Hermes counted an 8,000-token acting request and a 230,000-token advisor request as one 238,000-token context. The fix measures context from the acting request.
After three compactions in one long turn, automatic compaction stopped. A new test runs five compactions in one turn.
I'm Shayan Bianconi, an independent AI product engineer based in Los Angeles.
My work includes model integration, installers, memory management, health checks, and documentation. My background is in audio, hardware, and simulation. I test changes on my own machines and publish measurements with their conditions.
I also maintain Apple HIG for Agents, which helps coding agents use Apple's interface design guidelines.
I'm open to full-time AI product engineering roles.